What BPI measures, and what its ranking leaves out
ESPN's Basketball Power Index is a predictive measure of team strength. Its job is to estimate how well a college basketball team will perform, rather than reward the neatest win-loss record or reproduce the AP poll. That purpose explains many apparent disagreements: the team with the more impressive accomplishments can be ranked behind a team the model expects to play better next time.
The NCAA's selection glossary distinguishes BPI's strength assessment from résumé measures. ESPN introduced the tool through its analytics operation, and its own launch coverage stressed that no single calculation could account perfectly for every basketball variable. Read BPI with that same distinction in mind: it is an organized estimate, not a verdict that ends a basketball argument.
Rating points are not ranking places
The rating and the rank carry different information. A rating expresses a magnitude of strength; a rank puts teams in order. ESPN describes the BPI scale in points above or below an average team. Moving from No. 30 to No. 20 does not automatically represent the same improvement as moving from No. 10 to No. 1. The gaps between the underlying ratings can be very different.
Consider a purely hypothetical table in which Duke has a rating of 15.0 and Kansas has 14.8, while another team sits at 10.0. The first two are almost level on that teaching scale. Their ordering should not persuade a fan that one is dramatically better. The third team is farther away even if the ranking table places relatively few teams between them. These are illustrative numbers, not current BPI ratings or a forecast for those programs.
That distinction helps when a ranking changes without an obvious dramatic event. A team can move several places because other teams were closely clustered. Conversely, an improved rating might leave its ordinal position almost unchanged if neighboring teams improved too. The table is comparative: a team's place depends on the entire field, not only on what happened in its own last game.
Start by identifying the season selected on ESPN's page and the date of the update. A completed-season table found through search should not be called a live preseason projection for the next roster. Then read the rating, rank and relevant explanatory labels together. The most useful question is how large the estimated strength difference is, followed by what the next matchup does to it. A ranking place alone cannot answer either part.
How ESPN turns team strength into a game prediction
A game forecast asks a narrower question than a national strength table: how likely is one team to beat this opponent under these conditions? The NCAA's BPI description includes opponent quality, possessions, game site, travel, rest and altitude among the relevant inputs. Those factors explain why comparing two table positions is not enough to recreate ESPN's matchup percentage.
Do not take the difference between two BPI ratings and label it ESPN's official point spread. A transparent teaching calculation can isolate one factor, but the published model has its own treatment of context and uncertainty. Without its current complete specification, a hand calculation cannot be presented as an exact reproduction. The same caution applies when converting a pregame strength difference directly into a win probability.
Why a road favorite can have the lower national rank
First identify the ranking beside the team name. A televised number often refers to the AP poll, which is a separate assessment. A visiting team ranked lower by voters can still be stronger in BPI and favored in the game. There is no mathematical conflict between those labels because they came from different systems.
Now suppose, purely for illustration, that Kansas is slightly stronger than Duke on a neutral court. Moving that hypothetical game to Duke's home court could reverse the favorite if the site adjustment outweighs the initial difference. That example shows how a lower-BPI home team can become the game favorite. It does not imply that every home team gets the same adjustment or that these programs currently occupy any particular rating position.
A 70 percent favorite can lose without a contradiction
A 70 percent win forecast leaves a 30 percent chance for defeat. It does not promise that the favorite will lead for 70 percent of the game, win by a certain margin or survive every late possession. A missed open three, a turnover against pressure or foul trouble can decide one contest without changing what the pregame probability meant.
To evaluate that percentage, a useful question is whether a large collection of similarly forecast games produces roughly the expected share of winners. A single upset cannot answer that. Neither can one successful prediction prove that the model is excellent. The probability should be assessed over many comparable forecasts, with the information available before those games began.
This makes BPI useful for setting expectations while preserving the reason to watch. A 70–30 matchup is meaningfully different from a coin flip, but the underdog's path is still real. Read the favorite as more likely, then examine the basketball mechanisms that could produce the less likely outcome. That is stronger analysis than treating every forecast as a binary promise.
Why projected wins are not a list of guaranteed results
Being favored in every remaining game does not mean a team is expected to win every remaining game. A favorite can carry a substantial chance of losing each individual contest. Across a long schedule, those chances accumulate. This is one reason a season projection can look pessimistic to a fan who has marked every favorable matchup as a win.
Consider a hypothetical four-game stretch for Kansas. The numbers below are invented to explain expectation, not taken from ESPN. Add the win probabilities to obtain the expected number of wins across those four games. That arithmetic does not require calling the two favorites automatic winners or the two underdogs automatic losers.
| Teaching example | Win probability | Contribution to expected wins |
|---|---|---|
| Game one | 80% | 0.8 |
| Game two | 60% | 0.6 |
| Game three | 40% | 0.4 |
| Game four | 20% | 0.2 |
| Total | Four different opportunities | 2.0 expected wins |
A team cannot actually finish that stretch with a fraction of a win, but an average across possible outcomes can be fractional. If each of five games gives a team a 60 percent chance, its expected total is three wins, even though it is the favorite five times. The projection describes the distribution of possibilities, rather than identifying exactly which nights become defeats.
Championship chances answer a different question again. Winning several elimination games requires surviving every step. In a deliberately simplified example with three independent games and a fixed 70 percent chance in each, the probability of winning all three is 0.7 × 0.7 × 0.7, or 34.3 percent. The team can be clearly favored each night and still be more likely to lose somewhere in the sequence than win all three.
That multiplication is a teaching example, not a reconstruction of BPI's tournament engine. Real paths contain changing opponents, updated information and dependencies that a simple fixed-probability illustration leaves out. Similarly, a conference-title projection can depend on what rival teams do as well as the team's own results. A 70 percent chance to win one game is not interchangeable with a 70 percent chance to win the league.
For schedule analysis, identify where the uncertainty concentrates. Two difficult road games may account for more projected losses than several home games combined. A fan deciding which stretch deserves attention should examine those opportunities individually rather than turn a projected final record into a predetermined script. Expected wins summarize possibilities; they do not reserve particular dates for losses. The next game still has to be played.
BPI, Strength of Record, NET and the polls answer different questions
Before arguing that one ranking is wrong, decide what you want to know. “Who would be stronger tonight?” differs from “Who has accomplished more?” and both differ from “Which team do the voters prefer?” BPI, Strength of Record, the NCAA Evaluation Tool and the AP poll are useful precisely because they do not all reduce the sport to the same question.
| Tool | Useful reading question | Common mistake |
|---|---|---|
| BPI | How strong is the team estimated to be going forward? | Treating it as a record-based reward table. |
| Strength of Record | How difficult was this win-loss record to achieve? | Calling it the same thing as predictive strength. |
| NET | How does the NCAA's sorting tool organize efficiency and results? | Assuming a rank automatically awards a bid. |
| AP poll | How do the media voters order the leading teams? | Reading the number as a game probability. |
NET combines a results-based Team Value Index with adjusted net efficiency. That makes “NET is just wins” and “NET is just an efficiency model” both incomplete descriptions. Its role in tournament evaluation also does not make it a replacement for the committee's broader assessment. No BPI position, poll position or single NET position should be advertised as an unconditional at-large ticket.
Strength and accomplishment can disagree
Suppose one hypothetical team has played strong opponents closely but lost several finishes. Another has converted those opportunities into signature victories while producing less convincing possession-by-possession play overall. A predictive model can prefer the first team; a résumé discussion can favor the second. Those conclusions are not mutually exclusive because the evaluation targets differ.
For a Duke or Kansas fan, that distinction improves a familiar debate. A narrow road loss might provide evidence that the team can compete at a high level. It is still a loss when discussing what the team has achieved. A model can learn something positive about strength without crediting the team with a victory that never happened. Likewise, a victory can strengthen a résumé without proving the winner would be favored in every rematch.
The NCAA committee evaluates teams, rather than running a public ranking through one automatic cutoff. That is why a broadcast may discuss results, road performance and availability alongside several computer measures. A model disagreement is a reason to inspect the evidence and definitions. It is not, by itself, proof that the process is inconsistent or that a fan's preferred table must be ignored.
Use the site's college basketball rankings guide for the wider landscape. For BPI specifically, keep the question narrow: estimated future strength first, then the particular matchup. Reach for accomplishment measures when the argument concerns what a team has already earned.
A better way to use BPI before tipoff
Use BPI as the starting estimate for a matchup, then ask what basketball evidence might challenge that estimate. A useful preview identifies the favorite, the degree of uncertainty and the mechanisms through which either team could win. Merely repeating a percentage adds less than explaining how a press, a rebounding advantage or a difficult ball-screen matchup could change the game.
Begin with information hygiene. Check the season, update date, opponent and venue. Verify that you are reading a pregame forecast rather than a live GameCast probability or a rating updated after the result. A forecast revised after a game should not be used to claim the model knew the outcome beforehand. A screenshot without its timestamp can be especially misleading during a rapidly changing week.
Next check availability through the school and reliable reporting. Do not assume that an immediately announced absence has already been incorporated into every public rating. A missing primary handler can change how a team handles pressure, while a missing center can affect rim protection and defensive rebounding. The right response is to identify what changed and which replacement is available, rather than invent an exact percentage adjustment.
Compare another well-defined metric if it helps, but remember that agreement between efficiency models is not equivalent to several independent witnesses. Different systems can draw on much of the same game evidence. A disagreement is most useful when you can explain its source: treatment of preseason expectations, opponent adjustment or the difference between predictive strength and résumé accomplishment.
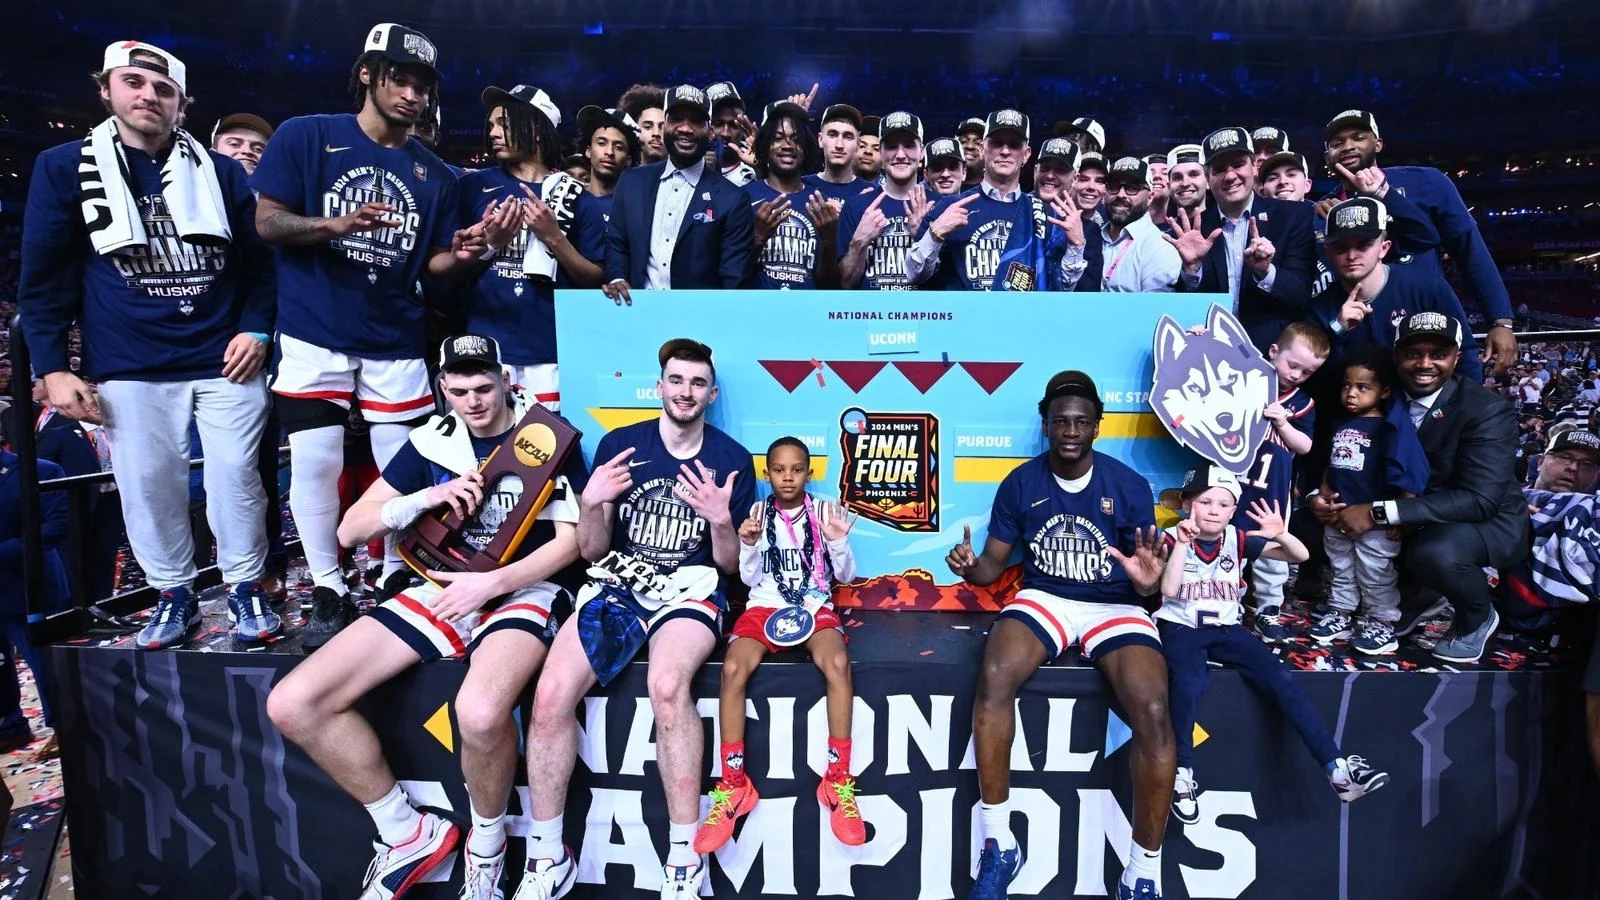
Then watch how the teams generate possessions. UConn's 2024 championship win over Purdue offers a historical reminder of why that matters. The Huskies won 75–60 and had a 13–2 advantage in bench points. That contribution does not prove any particular pregame forecast correct; it shows a concrete way lineup roles can influence the result beyond a national ranking. A prediction label cannot tell the full story of how a game is won.
A manageable pregame routine is to note the model favorite, identify one credible underdog pathway and name the evidence that would strengthen or weaken it. If the underdog needs offensive rebounds, watch whether it creates second chances without surrendering transition baskets. If it needs three-point variance, examine whether the offense actually produces clean attempts. Those are testable basketball observations, not excuses added after the score is known.
Find the actual matchup on today's game list and confirm the viewing option in the TV schedule. BPI is most useful when it sharpens what you watch. Let the probability frame expectations, and let the possessions reveal whether the underlying matchup argument survives contact with the game.
Sign in with Google to join the discussion.